Decision Models vs. CVE Data

Ollama’s new decision endpoint, Cloudflare’s Clef models on a MacBook, and two questions asked of all 27,489 CVEs published in the last 60 days: does the description say why the bug matters, and is it clear?

I read the announcement and had a weekend project before I finished it, because the question I care about most in the CVE Program has always been a classification problem: can a defender read this CVE and know why it should care?

The announcement was Ollama 0.35.1 adding Cloudflare’s Clef and Clef Flash to a new kind of model it started supporting in 0.35. They don’t write text. You hand them some state and a set of typed questions, and they hand back choices, yes-or-no probabilities and scores, with nothing to parse. That is a classifier that runs on my laptop, which is exactly the shape of the problem.

I already track how CNAs fill in their records at cnascorecard.org, but that only covers the structured fields a parser can read. The part I have never been able to check at scale is the prose, the one field every scanner shows an operator. So I asked Clef two things about every CVE published between August 4 and October 3, 2026. Does the description establish a security impact? And how clear is it for a defender?

Full disclosure: I serve on the CVE Program’s Quality, Automation and Consumer working groups. Nothing here is a CVE Program position.

TL;DR

Clef Flash, the 9B model, answered both questions for every new CVE at a median of under a second each on a laptop, with no API key and no bill. Outside the Linux kernel, 989 of 23,736 descriptions (4.2%, about one in 24) never say what an attacker could do. The kernel is its own case: its published policy leaves impact to the user, so 3,661 of its 3,753 records don’t state one either, which takes the all-CVE figure to 4,650 of 27,489 (16.9%). Flash on its own is too strict, so Clef 27B re-reads everything it flags as “no impact” outside the kernel, and 27B overturned 1,198 of 2,187 (54.8%). Against 129 published CVEs I labeled by hand, that two-step answer caught 15 of the 16 I said state no impact and never called one of my yeses a no.

Key Statistics at a Glance

Metric Value
CVEs published, August 4 to October 3, 2026 27,489, from 283 CNAs
No security impact stated, outside the Linux kernel 989 of 23,736 (4.2%)
No security impact stated, Linux kernel CNA (by policy) 3,661 of 3,753 (97.5%)
No security impact stated, all CVEs 4,650 of 27,489 (16.9%)
Large CNAs with zero such descriptions Microsoft, Oracle, Chrome, Wordfence, WPScan (5,666 records)
Descriptions rated Good or better for clarity (Flash, which runs generous) 69.7%
Clef Flash vs Clef 27B, same impact answer (published records, development sample) 402 of 428 (93.9%)
Impact answer vs my hand labels (Flash, then 27B) 128 of 129 (99.2%)
Clarity vs my hand labels (Flash), correlation 0.71
Clef Flash median time per description 0.84 seconds
Hardware A MacBook Pro I already own (M5 Pro, 64 GB)
API bill None

A Model That Only Answers Multiple Choice

Clef is a 27B model fine-tuned from Qwen 3.8, and Clef Flash is a 9B model fine-tuned from Qwen 3.5. Both are Apache 2.0, with weights on Hugging Face (Clef, Clef Flash), and both run locally from the Ollama library (clef, clef-flash; ollama pull clef-flash is about 10 GB). Cloudflare also hosts them on Workers AI, but everything here ran on my laptop. They are called through /v1/systemone, the decision endpoint Ollama added in 0.35, with a block of state and up to 64 named questions. Each question is one of three types:

Type What comes back
choice One of 2 to 26 options, with a probability for each
noul A single probability that the answer is true
score A position on an ordered scale of 2 to 26 levels, with a probability for each level

Here is one real request from the run, trimmed. The state is the CVE’s title and description, and the questions are written in plain English with a description for each answer:

{
  "model": "clef-flash",
  "state": {
    "title": "Arbitrary File Read in Google Agent Development Kit (ADK)",
    "description": "A Path Traversal vulnerability in the builder endpoint in Google Cloud Agent Development Kit (ADK) versions 1.9.0 through 1.21.0 on Python allows an unauthenticated remote attacker to read arbitrary files using a crafted file_path query parameter."
  },
  "questions": {
    "security_impact_stated": {
      "type": "noul",
      "instructions": "Does the description establish a security impact, that is, explain or clearly imply how an attacker could gain access, capabilities, or information they are not authorized for, or deny service to others? ...",
      "criteria": {
        "false": "No security impact is established: it describes a bug, a code change, or a fix ...",
        "true": "A security impact is stated or clearly implied ..."
      }
    },
    "impact_basis": {
      "type": "choice",
      "instructions": "How does the description support (or fail to support) a security impact?",
      "criteria": {
        "stated_explicitly": "...",
        "implied_by_weakness": "...",
        "bug_fix_only": "...",
        "not_security_relevant": "...",
        "insufficient_information": "..."
      }
    },
    "desc_clarity": {
      "type": "score",
      "instructions": "Rate how clear, specific, and useful the description is for a defender ...",
      "criteria": [
        "Unusable ...",
        "Poor ...",
        "Adequate ...",
        "Good ...",
        "Excellent ..."
      ]
    }
  }
}

And what Flash returned for CVE-2026-79707 (from my development run, where these three questions rode along in a bigger request):

{
  "security_impact_stated": { "type": "noul", "noul": 0.882 },
  "impact_basis": {
    "type": "choice",
    "choice": "stated_explicitly",
    "confidence": 0.63,
    "probabilities": {
      "stated_explicitly": 0.845,
      "implied_by_weakness": 0.098,
      "bug_fix_only": 0.029,
      "insufficient_information": 0.015,
      "not_security_relevant": 0.013
    }
  },
  "desc_clarity": {
    "type": "score",
    "score": 3.35,
    "probabilities": {
      "0": 0.010, "1": 0.019, "2": 0.042,
      "3": 0.465, "4": 0.464
    }
  }
}

That is the whole appeal. No regex over a chat reply, no “please respond in JSON”, no answer that wanders outside the options. In every request I sent, the output token count came back zero, because the model scores the options rather than writing anything.

Worth knowing before you build on it: a choice question tops out at 26 options, and cost scales with the number of questions. On this laptop the 27B model takes about 0.6 seconds per question once a request carries eight or more, and 2.0 seconds even for a request with only two. Sending requests in parallel bought me nothing, because on my setup Ollama answers decision requests one at a time. Ask the questions that earn their time.

Two Questions and Nothing Else

Does the description establish a security impact? Not “is this a vulnerability”, which the text often can’t settle. Just: does the description say, or clearly imply, what an attacker could do? A follow-up choice asks how: it says outright, it names a vulnerability class like SQL injection whose impact is understood, it describes only the bug or its fix, it has no security angle, or there isn’t enough to tell.

How clear is the description for a defender? A score from 0 (Unusable) to 4 (Excellent), with the levels written out: Adequate means it names the product and the problem but leaves out versions, the attacker or the impact; Excellent has all of them.

Clef only ever sees the title and description. It never sees the CVSS vector, the CWE, the affected-product data or the references. That is deliberate.

Outside the Kernel, One in 24 Never Says Why It Matters

Outside the Linux kernel, 989 of 23,736 descriptions (4.2%, about one in 24) don’t establish a security impact, and they come from 87 of the other 282 CNAs. Count the kernel and it is 4,650 of 27,489 (16.9%), but the kernel’s 3,661 are a policy, not an oversight, and they get their own paragraph below.
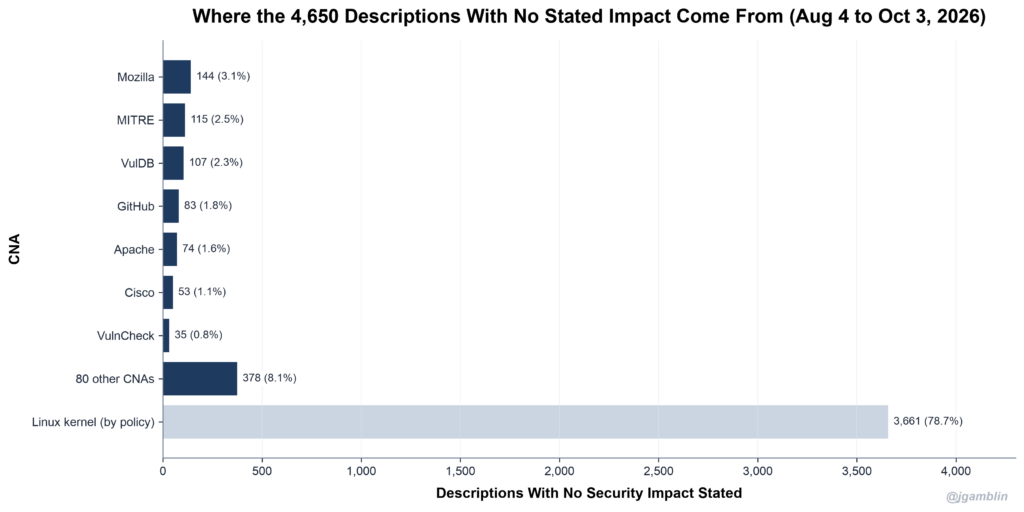
Where the 4,650 descriptions with no stated impact come from: Mozilla 144, MITRE 115, VulDB 107, GitHub 83, Apache 74, Cisco 53, VulnCheck 35, 378 from 80 other CNAs, and 3,661 (78.7%) from the Linux kernel CNA by policy

A selection, including three small CNAs (30 to 43 records) whose percentages move a lot on a few records:

CNA Descriptions No security impact stated
Linux 3,753 3,661 (97.5%)
Tanium 30 28 (93.3%)
Qualcomm 31 22 (71.0%)
Mozilla 250 144 (57.6%)
VMware 99 29 (29.3%)
Drupal 43 12 (27.9%)
Cisco 254 53 (20.9%)
Apache 454 74 (16.3%)
MITRE (CNA of Last Resort) 1,011 115 (11.4%)
Apple 295 30 (10.2%)
VulDB 1,587 107 (6.7%)
GitHub 2,836 83 (2.9%)
Microsoft, Oracle, Chrome, Wordfence, WPScan 5,666 0

The Linux kernel CNA tops that table on purpose. Its published policy is to assign a CVE to any bug fix it identifies and to leave applicability to the user, so its records are the fix commit message under “In the Linux kernel, the following vulnerability has been resolved”. CVE-2026-90222 explains in careful detail how a request buffer can be freed while the NFC driver is still sending it, and never says what an attacker could do with that. Clef 27B gives it 0.042 for a stated impact and files it under “bug or fix only” at 0.921. That policy is also why the kernel accounts for 78.7% of every description in the window that states no impact.

Qualcomm’s flagged records read like “Memory corruption while processing rear sensor IOCTL calls.” Mozilla’s flagged ones are longer but built the same way: “Use-after-free in the DOM: Streams component. This vulnerability was fixed in Firefox 156…” A bug class and a component, with no attacker and no consequence. Mozilla’s severity lives in its linked advisories, which Clef never sees.

Tanium’s row is the one I don’t trust. Its records read “Tanium addressed a SQL injection vulnerability in Asset.” A named SQL injection counts as an impact everywhere else: of the 1,968 descriptions in the window that name SQL injection or cross-site scripting, five are scored “no impact”, and four of those five are Tanium’s. Even “Tanium addressed an information disclosure vulnerability in Discover” names its consequence. My guess is that “Tanium addressed…” reads to the model as a patch note. None of my hand labels is a Tanium record, so treat that 93.3% as the model’s quirk, not Tanium’s.

All 12 of Drupal’s are “Unsupported” advisories, which the Drupal Security Team publishes when a module has a known security issue its maintainer hasn’t fixed, and the advice is to uninstall it. CVE-2026-76782 reads, in full: “Vulnerability in Drupal Screenshot. This issue affects Screenshot versions: *.*.” Even “uninstall it” would say more than that.

Clarity Follows the Template

The corpus averages 2.7 on the 0 to 4 scale, and 69.7% of descriptions rate Good or better. That is Flash’s line for Good, and Flash is generous: on my 129 hand labels it called 55% Good or better and I called 34%, so read 69.7% as high.
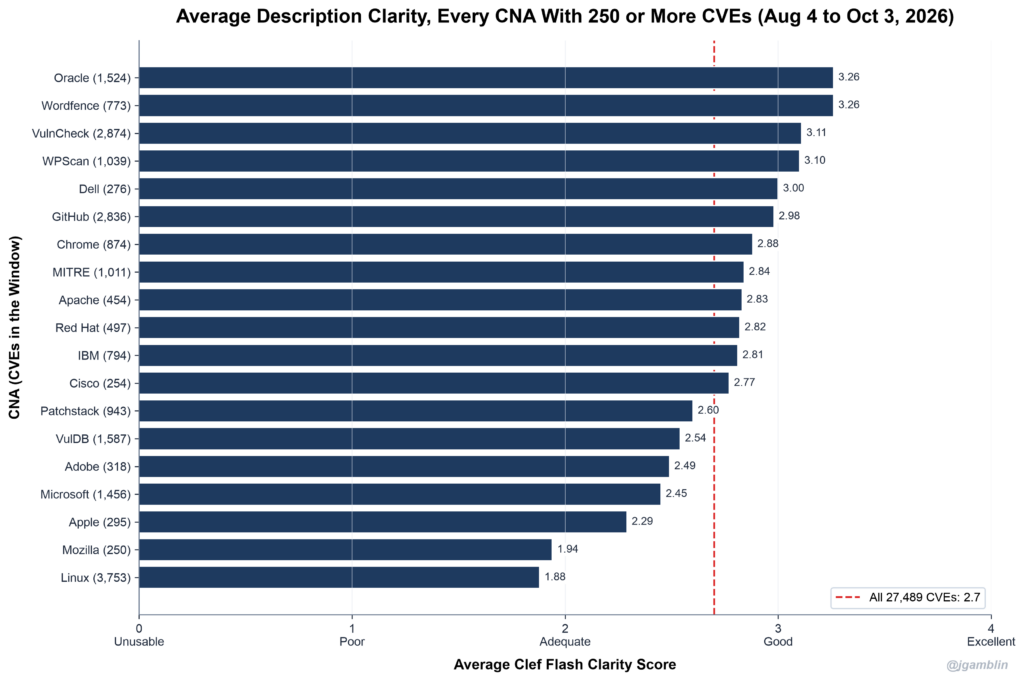
Average Clef Flash clarity for the 19 CNAs with 250 or more CVEs, from Oracle and Wordfence at 3.26 down to the Linux kernel at 1.88

The CNAs at the top write to a template that names the product, the versions, the attacker and the outcome, and it shows. Clarity also catches things no rule check would. 53 of Cisco’s 254 CVEs open with “As part of Cisco’s ongoing commitment to proactive security and product quality”, then describe a hardening release that fixes “multiple” internally found issues. Those 53 are exactly the Cisco records with no stated impact; the other 201 all have one.

Microsoft is the other case worth a look. Every one of its 1,456 descriptions states an impact, yet it averages 2.45 for clarity. Its descriptions follow one short formula (weakness, component, attacker, outcome), none of the 1,456 carries a version number, and 52 of them are the same sentence. The versions are in the structured affected data, which the rules allow; Clef just can’t see them.

The Small Model Needs a Second Look

My plan was to run Flash on everything and use 27B as a spot check. Apple killed that plan. Flash on its own said 126 of Apple’s 295 descriptions (42.7%) stated no security impact. Apple’s records end with a line like “An app may be able to bypass sandbox restrictions.” That is a stated impact. Flash gave CVE-2026-84577 a 0.328 and filed it under “bug or fix only”. It was reading Apple’s terse house style as an absence.

So the impact answer is a cascade. Flash reads everything. Clef 27B, about three and a half times slower on the same two questions (2.0 seconds against 0.59), re-reads every description outside the Linux kernel that Flash flagged as stating no impact. For the kernel, it re-reads a sample of 333 as a check. Where 27B has re-read a record, its answer wins.

Flash said “no impact stated” Re-read by 27B 27B disagreed
Outside the Linux kernel 2,187 1,198 (54.8%)
Linux kernel 333 19 (5.7%)

After the re-read, Apple drops from 42.7% to 10.2%, Mozilla from 70.8% to 57.6%, and the corpus from 5,867 “no impact” calls to 4,650. 27B gives CVE-2026-84577 a 0.873.

It doesn’t fix everything. All 30 Apple records still counted as “no impact” name a consequence, and five of them are “An app may be able to cause unexpected system termination”, which 27B scores 0.448 while filing it under “stated explicitly”. The two answers contradict each other. That’s the edge of the instrument, and those 30 are in the 4,650.

The cascade also has a blind spot: 27B only ever re-reads Flash’s “no” calls. Outside the kernel, where it happened to read Flash’s “yes” calls, it flipped 1 of 341. Scaled to all 21,549, that is about 60 records wrongly counted as stating an impact, so 4.2% may be a quarter point low. In the kernel sample it flipped 19 of 333 “no” calls, which would be about 190 kernel records wrongly counted as stating none, so the all-CVE 16.9% is, if anything, half a point high.
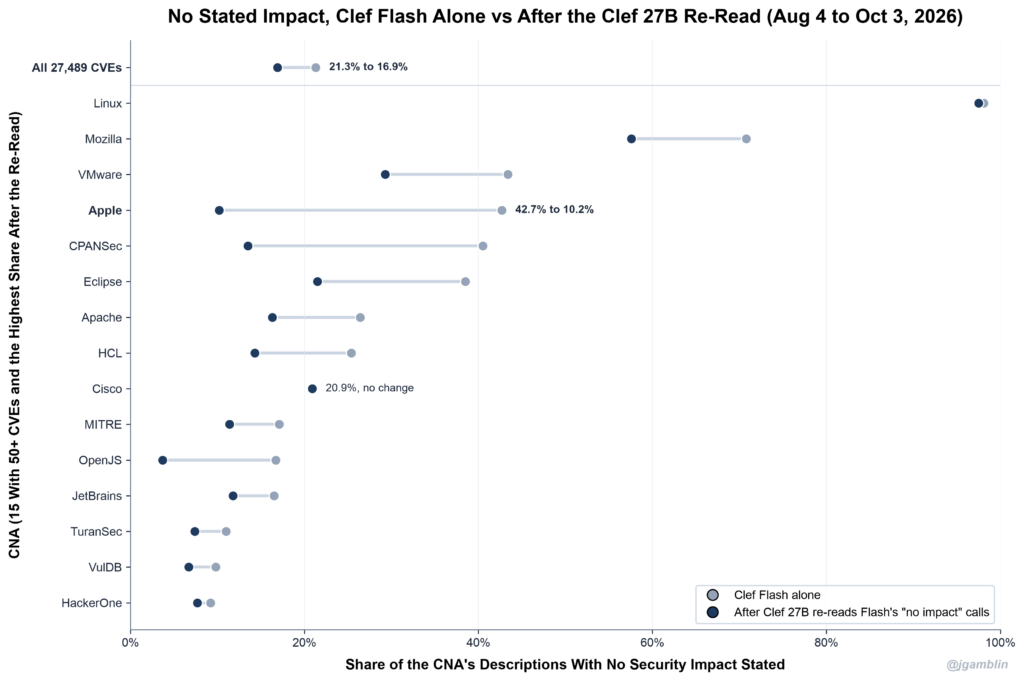
Dot plot of each CNA's no-impact share, Clef Flash alone versus after the 27B re-read; Apple falls from 42.7% to 10.2%

Clarity stays on Flash alone, so every CNA is scored by the same model. On the 529 development records both models scored, their clarity scores correlate at 0.87.

Checked Against My Own Labels

Agreement between two models only tells you they agree. So I built a small local web app and labeled 150 CVEs by hand: up to three per CNA from the last 30 days, plus 21 rejected records (everything below uses the 129 published ones). I answered the same two questions without seeing either model’s answer until I had committed to mine, and 149 of the 150 labels came after the question wording was frozen.

On the 129 published records Agrees with me Said “no impact” when I said yes Said “impact” when I said no
Flash alone 121 (93.8%) 7 1
Clef 27B 128 (99.2%) 0 1
Flash, then 27B on what it flags 128 (99.2%) 0 1

Every one of Flash’s seven misses was the too-strict kind, and the 27B re-read fixed all seven, which is the case for the cascade in one row. Worth being precise about what 128 of 129 means, though: I said “no impact” on only 16 of the 129, so a model that always said “impact” would score 113 (87.6%). The real result is that the cascade caught 15 of my 16 and never called one of my yeses a no. I also tried a stricter version of the impact answer, which put the headline at 15.4%. It agreed with my labels on 124 instead of 128, so the plain answer stayed.

The one miss is CVE-2026-77249, where a caller-controlled Jira URL “can redirect that unhooked request to an internal address, bypassing the redirect checks…” I read that as not saying what an attacker gets. Both models lean the other way, and the record’s own title says “redirect-based SSRF”. They have a point, which makes that miss more likely mine than theirs.

On clarity, Flash tracks me with a correlation of 0.71 and lands on exactly my level, after rounding, 72.1% of the time; always guessing 2 would get 62.8%. I never used the top or bottom of the scale, so “within one level” would mean nothing here. Flash runs about a quarter of a level generous: it averaged 2.37 on the ones I called 2 and 3.05 on my 3s. 27B was about as close as Flash.

As for the sample: capping it at three records per CNA means it holds far fewer Linux kernel fix logs than the corpus does, so it tests the hard cases outside the kernel more than the easy ones inside it. The labels also come from the same 30-day slice I used to develop the questions, so this is an in-sample check. And 150 records labeled by one person on a Sunday morning is a check, not a benchmark.

The lesson I would hand to anyone building on Clef: a small model is a fine screen and a poor judge. Running 27B on only the 2,520 records it needed to see was about a tenth of the work of running it on everything.

What It Cost

Flash takes a median of 0.84 seconds per description (14,870 timed requests, 90th percentile 0.98 seconds), which is about 6.4 hours of work for all 27,489 on an M5 Pro MacBook Pro with 64 GB. 2,434 of the 2,520 Clef 27B re-reads happened during the mess described next, at a median of 4.4 seconds. Measured on its own, 27B answers the same two questions in a median of 2.0 seconds (661 earlier requests), which is about an hour and a half for all 2,520. There was no API bill, no key to manage and no data leaving the laptop.

The wall clock was longer than that, and it was my fault. For about nine hours I had two Claude Code sessions both babysitting the run, each chaining the same chunks against the same queue in the same order. So 12,003 Flash answers and 2,438 27B answers were each asked twice, a few seconds apart, and each copy ran at half speed. The answers were identical, so nothing in the results changed. ps would have told me in a second.

Every CNA, Check by Check

The two answers sit in a per-CNA table alongside the parts a parser handles without any model: 23 checks, 16 of them mapped to CNA Operational Rules 4.1.0 and the rest data-format checks, run on every record in three seconds. Among them, 5,097 records (18.5%) leave the CNA’s problem-type field empty, including every record from the Linux kernel CNA and from Mozilla. Rule 5.1.7 makes identifying the type a MUST, but a CNA can meet it in the description, and Mozilla’s usually do. And 1,947 records (7.1%) share their description word for word with another CVE, which rule 5.1.1 discourages but the rest of the record can make up for. Adobe has 72 Experience Manager CVEs sharing one sentence. Microsoft has 52 sharing “Heap-based buffer overflow in Windows Biometric Service allows an authorized attacker to elevate privileges locally.” There is no combined score. Each rule check and each Clef answer is its own column, so you can sort by the one you care about. The per-CNA page is here.

What the Instrument Can’t See

Clef reads the title and description and nothing else, so a terse record that links a thorough advisory scores as terse. That is the right test for “is this record usable by itself” and the wrong test for “did the CNA do its homework”.

The check on those numbers is 150 hand labels from one labeler, and both questions are judgment calls. Reasonable people will put the line for “states an impact” in slightly different places, as CVE-2026-77249 shows.

If You Run a CNA

Put the attacker and the consequence in the description: who can do it, from where, and what they get. “An app may be able to bypass sandbox restrictions” is enough. “Memory corruption while processing rear sensor IOCTL calls” is not. If 52 of your CVEs share one sentence, the sentence isn’t doing its job.

If You Consume CVE Data

Outside the kernel, about one description in 24 won’t tell you why the bug matters. For kernel CVEs, by the kernel’s own policy, almost none will. When it doesn’t, you’ll need the CVSS vector, the references or the vendor advisory to find out. A model can tell you which records those are in under a second each, on a laptop.

What Didn’t Make the Cut

This started as a proof of concept, and I asked Clef plenty of other things on a sample of 300 CVEs first: whether the CVSS score was right, whether the CWE fit, and whether the record described a real vulnerability at all. CVSS came out as a reasonable second reviewer, about level with the other local models I tried. CWE caught real mistakes, like an out-of-bounds write filed as an out-of-bounds read, but I had nothing independent to confirm its other calls. And “is it a vulnerability” can’t be answered from the text, since CVEs later rejected as invalid read just as convincingly as the rest. Asking whether the description states an impact is the version of that question the text can answer. The experiments are in the repo if you want to pick them up.

Methodology and Reproducibility

  • Data: CVE List V5 from a local clone of CVEProject/cvelistV5 at commit 70f91a3c4fb4 (October 3, 2026, 13:55 UTC). All 27,489 PUBLISHED records with a datePublished in the 60 days before that commit, selected by publish date rather than ID year.
  • Models: Clef Flash (9B) and Clef 27B through Ollama’s /v1/systemone decision endpoint (Clef needs 0.35.1 or later), on an M5 Pro MacBook Pro with 64 GB of memory. Inputs are the record’s title and description only. Questions are versioned YAML in the repo, and answers are cached by question wording, so changing a question re-asks only that question.
  • Cascade: Flash answers both questions for every record in random order. Clef 27B re-answers the impact question for every record Flash marked “no impact” outside the Linux kernel CNA, plus a sample of 333 Linux kernel records as a check, and its answer is used where it exists. It never re-reads Flash’s “impact” calls. Every one of the 27,489 descriptions has a final answer.
  • Rule checks: 23 checks, 16 mapped to CNA Operational Rules 4.1.0 and 7 format checks on CWE IDs (against the CWE v4.20 catalog) and CVSS vectors, each reported as the share of a CNA’s records that pass.
  • Hand labels: 150 CVEs (129 published, 21 rejected), up to three per CNA from the last 30 days, labeled blind to both models’ answers; 149 of them after the question wording was frozen on October 3. They are in the repo.
  • Announcements and docs: Cloudflare’s Introducing Clef, Ollama’s decision models post and decision API docs, and the release notes for Ollama 0.35.0 and 0.35.1.
  • Code and per-CNA page: github.com/jgamblin/CLEFCVE and the per-CNA page.
  • Data collected October 3, 2026; Clef runs completed October 4, 2026.

I set out to test CVE descriptions and spent most of the weekend testing my own questions. What I came away with is a new kind of tool. A decision model can’t ramble and can’t answer outside the options, and Clef Flash made 27,489 judgment calls on a laptop in about six and a half hours of compute. Nimble, Tev1 and Clef all arrived in Ollama within a week of each other, so this is the start of the category, not the end of it. I will for sure keep pointing these models at CVE data, and the questions are in the repo if you want to beat me to it.

RBP Tracker: Counting the CVE IDs the CVE List Cannot See

A new RogoLabs site lists Reserved but Public CVE IDs: 2,315 of them on September 14, drawn from 17 public advisory feeds, refreshed every six hours, and held a week before they appear.

The first version of this tracker reported that none of the CVE IDs it found existed in the CVE List, in any state. It was July, the script was a week of evenings, and it asked the CVE Services API about every CVE ID cited in a pile of distribution and GitHub advisories but missing from the List. The API returned 404 for all 456 of them, so the report said DNE, does not exist, 456 times.

Every one of those IDs existed. They were reserved. I was asking /api/cve/, which answers 404 for a reserved ID and for an ID nobody ever issued, and cannot tell you which. There is a second endpoint, /api/cve-id/, that returns the real state for any ID, unauthenticated, and every one of my 456 came back RESERVED. Re-checked 32 days later, 224 of them had published, which is how I know they were real.

rbptracker.org is the corrected version of that script, run in public, with its mistakes written down. It is a RogoLabs project, which means my own time and nobody’s roadmap.

What a Reserved but Public CVE ID Is

The term is the Program’s own, not mine. It has been in the CNA Rules since version 3.0 in March 2020, the Program was charting RBP counts in its quarterly reports by 2021, and it is in the glossary and RBP Policy v2.0.0 today. The definition: a CVE ID in the Reserved state that a public source already references, while the CVE Record itself is unpublished.

The advisory is out. A reserved ID has no CVE Record yet, so the bulk CVE List cannot carry it: everything in cvelistV5 is PUBLISHED or REJECTED. The List is doing its job. It just means anyone who wants the reserved IDs has to build the list from somewhere else. NVD has no entry, EPSS has no score, and enrichment has nowhere to attach. A scanner that keys on CVE Records learns about the bug when the record lands. One fed by the distributions’ own data may already know.

RBP Policy v2.0.0, approved by the CVE Board on August 13, expects a record within 72 hours of the CNA disclosing, or of the CNA becoming aware that someone else did. I cannot see either moment from outside, so the site counts days public. It never says overdue. There is an enforcement process, and it runs inside the Program: no public list of RBPs, no log of who was notified. The one thing anyone can see is the state of each ID, so the state is what this site publishes.

Seventeen Feeds, Every Six Hours, Seven Days Before a Row Appears

Every six hours a GitHub Action reads 17 public advisory sources, pulls out every CVE ID they cite, and asks the reservation endpoint for each one’s state.

KindFeeds
DistributionsDebian, Ubuntu (its tracker and its OSV export), Alpine, Amazon Linux, Red Hat, Arch
VendorsMozilla, MSRC, Samsung
Coordinators and disclosure programsJVN, CERT/CC, ZDI
AggregatorsOSV, GitHub’s advisory database, GitHub repository advisories polled one repo at a time
CSAF18 publishers, Red Hat and SUSE to CERT-Bund and CISA

RESERVED plus a public reference is a row.

Nothing gets listed until it has been public for seven days, more than double the 72-hour window, so a slow feed does not explain a row. What the buffer cannot do is tell an overdue record from an embargo. Nothing I can see from outside can, and some of these rows are legitimately held. There is no takedown form either. Every row is an ID the Program itself says is reserved, cited by an advisory that has been public for a week, and the row I cannot help is the accurate one that lands in the middle of somebody’s coordinated disclosure.

It publishes a static site plus JSON, CSV and a dated archive to GitHub Pages. No server, no database, and no credentials beyond the token GitHub Actions hands every workflow. The hosting bill is the domain.

September 14 run
Rows listed2,315, a floor
Median days public67
Public 180 days or more312 (13.5%)
Public a year or more222 (9.6%)
Oldest1,314 days, a lone reference in a CERT-Bund CSAF document from February 2023
2026 IDs2,016 (87.1%); the rest are 152 from 2025, 110 from 2024, 37 from 2023
Rows seen by exactly one feed1,458 (63.0%), 1,014 of them repository advisories no other feed can carry
CNAs the feeds have seen publish at least three times in the last four years268 of 539 on the roster (49.7%); 313 seen at least once; 49 of the 50 highest-volume

Worth saying what two of those rows mean. “Days public” counts from the earliest date any feed shows me, which is a floor. For 55 rows that date is a distribution tracker entry rather than an advisory, and since nothing under a week gets listed, the median is over rows that had already cleared the buffer. The oldest row is exactly the kind I trust least. One reference, three and a half years old, is the row most likely to be a typo of a neighboring ID, and I have no way to check. 297 rows carry nothing but the ID.

And “floor.” The feeds see the published output of 268 of the 539 CNAs on the roster, so the other half is out of view no matter what it does, and the count went from 522 rows on August 22 with 9 feeds to 2,315 today with 17. That series measures how far the feeds reach and says almost nothing about whether RBPs are rising. The biggest step in it was one feed: repository-level GitHub advisories with no package ecosystem do not appear in GitHub’s global advisory database, and that feed alone accounts for 1,318 of today’s rows, 1,014 of which appear nowhere else.

The question I get most is whether this is publication lag. Since August 21 the tracker has watched 527 tracked IDs publish, and for the 514 I could time, the median had been public for 48 days when its record appeared.

That is three and a half weeks of closures from a population that was already old when the tracker started, and one batch moved it: 29 CVE-2023 IDs published on September 14, supplied most of the year-plus tail, and lifted the median from 41 to 48 overnight. So 48 days describes the IDs that happened to publish in three weeks, not a typical RBP. It does rule out the boring answer: these rows are not a feed running a day ahead of the List. I am not going to give you the share that published inside 72 hours. Nothing under a week old gets on the list, and the ten closures under seven days all predate that rule, so the number would be about my buffer, not about the Program.

Two More Things I Got Wrong

The wrong endpoint was not the only correction. Two more changed what the site is allowed to claim.

What I believedWhat turned out to be true
The policy had a 5% threshold I could measure the list againstThat was RBP Policy v1.0, pulled from cve.org in January 2022 and still mirrored by third parties, which is how I found it. v2.0.0 has no numeric threshold. The scoreboard came out
A seven-day buffer would filter out coordinated disclosuresAn embargo and an overdue record look identical from outside. No buffer length separates them. The buffer rules out latency, which is a narrower claim, and the method page now says so

The rest of the list, including the morning the status page claimed a 164.3% publish rate, is in the repo’s NEXT.md and will probably be a talk.

The Thing I Actually Need: More Feeds

The most useful thing you can hand me is a source I am not reading. The count is bounded by what the feeds can see, and every feed on the site was scored before it went in. Two questions for any candidate: does it show me a CNA nobody else does, and has it ever cited a CVE ID before the record existed? EUVD fails the second. It publishes because a record published, so it can never be early. The feeds that pay off publish on their own clock: CERT/CC when coordination ends (300 IDs, 12 rows nobody else sees), ZDI when its disclosure timeline runs out (23 of its 38 rows the same).

So: a public page or feed that cites CVE IDs before the record publishes, fetchable without a login, in any format I can parse. Distribution security trackers, vendor PSIRT pages, CSAF endpoints, coordinator advisories, mailing list archives. I will run it through the same two questions and post the scorecard either way, merge or not. If you know one, open an issue with the URL and, if you have it, one CVE ID it cited while the ID was still reserved.

If You Consume the CVE List or Run a CNA

If you consume the CVE List: a 404 from /api/cve/ is not evidence that an ID was never allocated. Ask /api/cve-id/. And the feeds already in your stack publish these IDs weeks before the record does: the IDs this tracker watched publish had a median of 48 days in public first. The JSON and CSV are at rbptracker.org, refreshed four times a day, with the caveats in the same file as the rows.

If you run a CNA: check your reserved IDs against your own advisories. Everything on this list was cited in public by somebody. On today’s run that somebody is most often a GitHub repository advisory (1,318 of 2,315 rows), and 393 rows are cited by a distribution, which usually means the fix shipped before the record.

Full disclosure: I serve on the CVE Program’s Quality, Automation and Consumer working groups, and nothing here is a Program position.

Notes

  • Site: rbptracker.org. The method, the policy quotations and the live pipeline health are at /method.html, /policy.html and /status.html.
  • Feed suggestions and anything else, including a row you think is wrong: github.com/RogoLabs/RBP/issues. The code that produced the row is public and so is the pull request queue. The two feed tests and every scorecard so far are in FEEDS.md and feedlab/.
  • Code: github.com/RogoLabs/RBP, Apache 2.0. 190 commits between August 20 and September 13; the suite is 1,272 tests, 1,207 of which run offline in about 25 seconds on my laptop.
  • RBP Policy v1.0 was removed from cve.org on 2022-01-25 per cve-website issue 835. The last CVE Program quarterly report I can verify carrying the RBP chart is Q2 CY2021, published 2021-07-28, in the old cve.org site archive.
  • Every number above is from the 2026-09-14 run (summary generated 12:57 UTC, code 8a29a842ab74), saved in data/, and will have moved by the time you read this. The closure figures are from the tracker’s resolution ledger on its data branch, same date; its earliest closure is dated 2026-08-21.

10,501 Radios in Seven Days: What a $69 Badge Heard at Summer Camp

Seven days of passive listening at BSides, Black Hat and DEF CON: 673 open networks, one beacon flooder, and what it takes to count devices honestly.

I have wanted to build one of these for a long time. A little screen on my bag that tells me what the air around me is actually made of, not just that there are networks nearby, but what they are. The thing that finally made it possible was the Pimoroni Tufty 2350 showing up at Adafruit: an RP2350B, a 2.8″ colour screen, WiFi and Bluetooth, a 1000 mAh battery in the box, and MicroPython already flashed on it. Sixty-nine dollars, and nothing to install before you can write a line of code.

The billboard view, mid-week. Thirty-three radios logged as devices, 259 in range right now, and 254 rotating addresses thrown away. That last number is what most of this post is about.

The other thing that made it doable was pairing with Claude for a week. I have built enough hardware side projects to know how they usually end, which is in a drawer, two thirds finished, blocked on the boring part. This one did not, and the reason is that the boring parts got done in the gaps between talks.

So: seven days, one badge, passive listening only. Here is what it found and, more usefully, everything I believed on Monday that turned out to be wrong by Sunday.

TL;DR

Seven days of Summer Camp produced 4,653 access points and 5,848 Bluetooth devices, all of it passive. No association, no probe requests, no packet capture. Just beacons and advertisements, which every device in the room broadcasts to anyone who bothers to listen.

The two findings I would put on a slide: 673 open networks, and one beacon flooder pushing 77 fake networks across all 13 channels, impersonating ISP defaults from six countries. And the correction that took the longest: my first device count was 8.8% inflated, because a badge that counts addresses is not yet counting devices.

Three caveats up front. This is a listening device, not an attack tool. It never associates and never captures traffic, and counts of rotating addresses are upper bounds by design.

Bluetooth scanning was active until Thursday. Active scanning sends a scan request, which means the badge was transmitting for the first three days. It ran passive from Thursday on, for reasons in the scanning section below. WiFi was passive throughout.

And it only hears 2.4 GHz. The Tufty’s radio module is single-band, so every access point number in this post excludes 5 GHz and 6 GHz entirely. Across 15,446 access point records all week, not one sat above channel 13. The real access point count in those buildings is meaningfully higher than 4,653.

Key Statistics at a Glance

MetricValue
Access points4,653
Bluetooth devices5,848
Seen on more than one day2,552
Open networks673 (14.5%)
WEP access points88
Fake networks from one emitter77
Spoofed network names39
Espressif (ESP32) devices544
Days carried7
Radio2.4 GHz only (no 5 GHz seen, ever)
Times the badge hung and recovered itself92 (Thu-Sun only)
Lines of MicroPython (the app)2,480

Somebody Was Flooding Fake Networks

The badge classified 88 access points as WEP, an encryption scheme broken since 2001 and shipped by essentially nothing built this decade. Worth being precise about what that means: the badge reads a driver auth-mode index rather than parsing the actual security element, so “WEP” here most likely means the privacy bit was set with nothing valid behind it. That is a fingerprint of a beacon generator, not of 2001-era hardware. What makes it a finding rather than a curiosity is that 77 of them had locally administered MAC addresses, meaning the hardware address was invented in software rather than burned in at the factory.

WEP plus an invented MAC is suspicious, but not conclusive on its own: plenty of legitimate multi-BSSID, mesh and phone-hotspot gear sets the locally administered bit too. What closes the case is the SSID list.

The network names close the case. Thirty-nine of them. Here are the ones that give it away:

CategoryNames
US ISPsxfinitywifi, optimumwifi, TWCWiFi, MySpectrumWiFi
UKSKY, Virgin Media, BTWiFi-with-FON
GermanyTelekom_FON, Vodafone Hotspot, FRITZ!Box 7490
Franceorange, SFR WiFi Mobile, FreeWifi
Netherlands / BelgiumKPN Fon, Ziggo, TELENETHOMESPOT
The free-WiFi trapGoogle Starbucks, McDonald's Free WiFi, Airport Free WiFi, Hotel WiFi
Universitieseduroam
Router defaultsNETGEAR, TP-Link, linksys, ASUS, setup
The restGuest, Home, HOME-, internet, wireless, WLAN, AndroidAP, iPhone, Samsung, DIRECT-, HP-Print, Netgear-5G, Starbucks WiFi

My first instinct was to call this a karma rig, and my own data says it is not one.

Karma is a response technique: it listens for a phone’s probe request and answers with the exact network name that phone asked for. Three of these names are bare wordlist prefixes, DIRECT-, HP-Print and HOME-, and no client has ever probed for those literal strings. That is not truncation on my end either; the same capture holds DIRECT-0F-HP PageWide Pro 577 and HP-Print-D7-Officejet 6600 at full length.

Two more tells point the same way. Every one of these is advertised with encryption set, but the real xfinitywifi and eduroam are open networks, so nothing would auto-join these anyway. And they are spread near-evenly across all thirteen channels, including 12 and 13, which are not legal in the US and where American phones largely will not associate. Everything else in the week clusters hard on channels 1, 6 and 11.

So this is a beacon flooder reading a name list off disk, not a rig fishing for associations. Most likely somebody’s ESP32 or an mdk4 demo, left running.

It ran on Monday and essentially never again. 76 of the 77 were first heard on BSides day one; exactly one more turned up on Friday. Across the entire DEF CON weekend the badge saw two WEP access points total: one called Hac-Man Contest Network on real TP-Link hardware with a burned-in address, and one more invented-MAC rogue broadcasting no name at all, which was the seventy-seventh and last of the flooded set.

I want to be careful here: this is almost certainly a demo, a village exercise, or someone’s research, and beacon flooding does not compromise anything by itself. It fills the air with names. But it is a good illustration of how little it costs to make a room look like it contains forty networks that do not exist.


What the Air Was Secured With

Wednesday was the densest WiFi day, which is Black Hat’s business hall doing what business halls do, and Friday was the densest for Bluetooth, which is DEF CON’s first full day. 2,552 access points and devices were seen on more than one day, which is 1,117 access points and 1,435 Bluetooth devices.

It is worth saying what that figure can and cannot mean. A device that rotates its address is structurally incapable of appearing on two different days in this dataset, so the multi-day count is not a measure of returning attendees. It is a census of hardware with no address privacy, and it looks like it: 90% of those returning Bluetooth devices have burned-in public addresses, led by casino hardware and the venue’s beacon estate.

673 open networks, 14.5% of everything seen. Most of that is the resort’s own guest WiFi, which is doing exactly what resort guest WiFi does. MGMResorts-WiFi alone accounted for 366 access points.

Worth repeating here: this is the 2.4 GHz picture only. Plenty of modern enterprise gear puts its best-configured, WPA3-capable radios on 5 GHz and leaves 2.4 GHz for the guest and legacy traffic, so the mix below is probably the least flattering slice of these networks rather than a fair sample of them.

WPA2 still dominates at 79.9%.

I had a paragraph here about WPA3 adoption being stuck at 3.7%. I cut it, because the badge cannot actually see WPA3, and the proof is sitting in my own capture: all 38 access points broadcasting the SSID DefCon-WPA3 came back classified as WPA2. The badge reads an auth-mode index from the radio driver, not the network’s actual security element, and a WPA3-only network lands in the WPA2 bucket by construction. Not one access point all week resolved as WPA3 on its own, which tells you about my instrument rather than about the buildings.

So the honest version is narrower: 3.7% advertised something the driver reported as WPA2/WPA3 transition mode, and I cannot give you a real WPA3 adoption number from this hardware.


What a Hacker Conference Is Actually Made Of

544 Espressif devices. That is the ESP32, and at DEF CON it is not IoT, it is badges. Within that 544, 134 advertise as Espressif Battery and another 66 simply call themselves Me, which is a picture of the independent badge scene that no attendance number captures.

The rest of the list is a Vegas conference centre being a Vegas conference centre. 685 devices on Panasonic’s Matsushita OUI, 158 of which identify themselves as IGT card readers, plus 71 more on Panasonic’s industrial block: almost certainly the casino floor advertising all week. I did not verify what any individual unit is, and I did not go looking. 564 Apple iBeacons, and not one of them is an Apple device. They are Texas Instruments, Silicon Labs and Murata modules on burned-in addresses: fixed wayfinding and retail infrastructure speaking Apple’s protocol, not a single phone among them.

And 93 Nintendo devices, 22 of them Pokemon GO Plus dongles, because it is DEF CON and people bring their Switch.


Counting Addresses Is Not Counting Devices

This is the part I actually want to write about, because the numbers above are only trustworthy because of it.

The badge shipped Monday counting addresses. It finished Sunday counting devices. Those are not the same thing, and across the week the gap was 8.8%.

That percentage is the effect on a week dominated by access points and casino hardware with burned-in addresses. In a dense, rotation-heavy room the same rules cut far harder, as the two examples below show.

Modern phones, watches, and earbuds re-randomise their Bluetooth address every fifteen minutes or so, specifically so they cannot be followed around. A naive scanner sees each rotation as a brand-new device. Four separate corrections, every one of them forced by real capture data rather than by reading a spec:

1. Apple Find My beacons rotate, but look permanent. A 96-minute walk logged 356 distinct Find My addresses, 116 of them inside a single ten-minute window. That is roughly 55 real devices. By the address bits they look static and permanent; in practice they re-derive every fifteen minutes.

2. All of Apple Continuity does it, not just Find My. An overnight capture in one hotel room logged 99 addresses labelled “AirPods”. That is a handful of earbuds re-randomising, not 99 pairs of AirPods in adjacent rooms.

3. Apple is not special. Microsoft’s Swift Pair and Google’s Fast Pair rotate exactly the same way. A single BSides afternoon logged 153 addresses announcing Swift Pair inside fifteen minutes, which was one spammer with an ESP32, popping “add a device” dialogs at everyone walking past.

4. A label only counts if it tells devices apart. This is the general version of the other three and the one I wish I had started with. Sixty-six addresses all calling themselves T-Dongle Biscuit are one dongle, not sixty-six. The badge now counts how many random addresses have worn each name and stops believing a name once too many have.

Applied to one overnight hotel capture, those rules turned 389 “devices” into 6: a fitness band, a Tile, and four things with real burned-in addresses. Applied to an airport concourse they kept 473 of 1,200, because a concourse genuinely is full of permanent hardware.

The lesson I would hand to anyone building this: your scanner’s device count is a claim about identity, and identity is the hard part. Everything else is just parsing.


It Hung 92 Times and Kept Working

This is the part I only understood at the end of the week, and it is the engineering I am happiest with.

On Thursday I found the badge frozen at DEF CON: screen stuck, USB dead, and it had been that way for 3 hours and 40 minutes. Somewhere in the RP2350’s firmware, or the shared radio, or the interaction between the two, something wedges hard enough that no Python is running at all. I still do not know what. I tested the WiFi/Bluetooth handover across 400 cycles, the interrupt workload at conference rates, flash writes racing interrupts at 1,600 times the normal rate, and every queueing race I could construct. All clean. It will not reproduce on a desk, and the one variable a desk cannot supply is a room with ten thousand people in it.

So rather than keep chasing it, I made it survivable. An eight-second hardware watchdog reboots the badge whenever the main loop stops. The log lives on flash and de-duplicates on restart, so a reboot costs about fifteen seconds and nothing else.

Then the telemetry showed it was happening 92 times.

Roughly once every fifteen minutes, and I never noticed a single one, which is exactly what you want a watchdog to feel like. That count covers Thursday through Sunday, because the health log that records restarts did not exist before Thursday, which means the true week total is higher than 92 and I cannot tell you by how much. It also counts only restarts while the badge was on battery, so my own resets on the bench are excluded.

Before the watchdog existed, the first hang of the day simply ended the day, which is why it had looked like “a couple of lockups” rather than a steady drumbeat. Measured downtime across those four days: about 1.6%.

The fix did have a knock-on effect worth knowing about. Every restart wiped the in-memory counters that stop one spammer being logged as sixty devices. The rule held perfectly within each session, but across 36 sessions on Saturday a single label still accumulated 62. Moving those counts onto disk took one evening, and Sunday came back with every shared label capped at exactly 8.

One caveat on that, since it affects the numbers earlier in this post: the cap runs per capture session, and each day is its own session. Across seven days a rotating label can still accumulate to roughly eight per day, which is why Tile appears 46 times in the week totals rather than 8. Public burned-in addresses are exempt from the cap entirely and always were, which is why the casino hardware counts are untouched by it.


What Changed, Day by Day

Every one of these came from the badge contradicting something I believed. Not one came from reading a specification.

DayWhat the data saidWhat I changed
Sat 1stThe interrupt handler was writing to a dict the main loop was walkingQueue from the interrupt, insert from the main loop
Sun 2ndThe battery died at 2,793 mV, not the textbook 3,300Rewrote the runtime model; 6h 27m became 9h 46m
Sun 2ndMean SSID was 7.7 characters in a 32-byte field, so 45% of the log was zeroesLength-prefixed records, halving the log
Mon 3rd356 Find My addresses in 96 minutes, from roughly 55 devicesRotating addresses counted, never logged as identities
Mon 3rdSomebody spamming pairing popups locked up the screenCap admissions per frame, detect and report floods
Tue 4th153 “Microsoft Swift Pair” addresses inside fifteen minutesSwift Pair and Fast Pair rotate too, same as Apple
Tue 4thThe billboard said DEVICES over a number that included access pointsSay RADIOS, because that is what it counts
Wed 5th50 real devices read as 507/second and latched the alarm foreverMeasure address novelty, not advertisement volume
Thu 6thFrozen at DEF CON: screen dead, USB dead, 3h 40m lostHardware watchdog, so a hang costs fifteen seconds
Thu 6thThe scanner was transmitting while the README said it never didSwitched to passive scanning
Thu 6thDeploys were failing silently and I was testing the old builddeploy.sh now proves the install landed, twice
Fri 7thNo idea what the badge was doing when it frozeBreadcrumb the current phase to flash before every long call
Sat 8th34 of 36 restarts died “running normally”, not in a blocking callConfirmed a real firmware hang, not my watchdog misfiring
Sat 8thRestarts wiped the counters, so one label reached 62Rebuild the counts from disk at startup
Sun 9thEvery shared label capped at exactly 8Nothing. It finally worked.

The pattern is the thing I would take away. Every single correction came from looking at what the badge actually kept, and every single one contradicted a reasonable assumption. The spec says static-random addresses are stable. They are not, for anything Apple, Microsoft or Google ships. The spec says a device name identifies a device. It does not, when sixty-six addresses share one.


Passive Is a Setting, Not a Category

Bluetooth scanning has two modes, and the difference matters more than it looks from the outside. Passive listens. Active sends a scan request to every device it hears, asking it to say a bit more about itself.

Active is the mode you reach for when you want good device names, and it is where I started. It is also, strictly speaking, transmitting, while the README I had written described the tool as passive. The code and the documentation had quietly drifted apart, and I only noticed while looking at the radio settings for a completely unrelated reason.

Switching to passive turned out to cost nothing. Measured back to back in the same room, passive drew 34.5 advertisements per second against active’s 57.6, and found 36 devices against 34. Fewer packets on the air, and no loss of identification: 63% of Sunday’s devices carried a name beyond their manufacturer, against 56% on the last full day of active scanning. Read the device delta as no meaningful difference rather than passive winning, since it is one test in one room.

Worth checking on anything you carry: “passive scanner” describes a setting, not a category of device, and the library default is not always the one you would have chosen.


Privacy, Since This Is the Part That Matters

This badge records identifiers belonging to other people’s devices, in a city full of people who did not consent to being in my dataset.

So, the rules I held myself to. MAC addresses are personal data under the GDPR and plenty of other regimes, and Summer Camp is an international crowd. The full capture with addresses never left my laptop; everything in this post is an aggregate. Rotating addresses exist precisely because people opted out of being followed, and the counting work above is not a way around that, it is the opposite: the badge deliberately refuses to re-identify anything that has asked not to be. And the log gets erased when the analysis is done.

Passive reception is broadly lawful. What you do with the results is the part with rules attached, and “I could” is not the same as “I should.”


What I Would Change for Next Year

A second radio, or a different one. The single biggest limitation of this build is that the Tufty hears 2.4 GHz and nothing else. Raspberry Pi’s RM2 module is Wi-Fi 4, single-band, and it shows: across 15,446 access point records I never once logged a channel above 13. Everything in this post about access points describes the least interesting half of the spectrum, because the modern, well-configured, WPA3-capable radios in those buildings are mostly sitting on 5 GHz where the badge is deaf.

That also means my WPA3 number deserves an asterisk. 3.7% is real for 2.4 GHz, and I would not be surprised if the true figure across both bands is several times that.

Fixing it means either a badge with a dual-band radio, or bolting an ESP32-C5 or similar onto this one and treating the Tufty as the screen and the brains. That is next year’s project.

Find the hang. Ninety-two recoveries a week is survivable, not solved. The watchdog turned an invisible catastrophic failure into an invisible trivial one, which is a real improvement, but I would rather know what wedges the chip. That needs either a logic analyser on the radio bus or a way to reproduce conference-scale RF density on a bench.

Ship the badge fully built. Everything in this post was tuned during the week it was being used, which is a terrible way to collect a clean dataset and a wonderful way to find bugs. Next year I want the counting rules settled before day one, so the whole week is measured the same way.


Build One

Everything is open source and the whole thing runs on a $69 off-the-shelf badge with no toolchain:

It identifies what it sees using 39,877 IEEE OUI prefixes and 3,988 Bluetooth SIG company IDs compiled onto the device, so there is no network lookup and no phoning home. It runs about ten hours on the internal battery.

If you build one, I would genuinely like to see what your city looks like. Find me on LinkedIn, X, Bluesky, or infosec.exchange.

And if you were the one running the beacon flooder on Monday: nice wordlist.

Hydrate, Hack, Repeat: Security Summer Camp 2026

My schedule, a new role at Empirical Security, and the CVE and vulnerability talks worth your time.

It is almost the first week of August, which means it is time to point myself at the desert one more time. BSides Las Vegas, Black Hat, and DEF CON all land back to back, and for me it is the same ritual it has always been: an exhausting, sunburned, over-caffeinated, absolutely amazing week of reconnecting with the people who make this industry worth being in. If you have never done all three in a row, a word of warning: hydrate, wear real shoes, and clear your calendar for the following Monday.

This year the trip feels a little different, because I am showing up with some news.

Big News: I Joined Empirical Security

A few weeks back I announced that I have taken on the role of Head of Research at Empirical Security. I wrote about why in Country Roads, Take Me Home, but the short version is that this is a homecoming. Empirical is where the math actually gets done: predictive models, EPSS, and the kind of data-driven vulnerability management I have been talking about for years, built alongside people I have wanted to work with again for a long time.

The thesis I keep coming back to is simple: you cannot run a data-driven VM program on top of abstracted, artificially grouped vulnerability data. The numbers make the case. The first half of 2026 produced 34,601 CVEs, up nearly 49% over last year, and only 0.24% of them have landed in the CISA KEV catalog. KEV is a conservative floor, not a full exploitation census, so the real number runs higher, but even generously, exploitation stays a small fraction of the total. You cannot triage that flood, let alone predict it, unless the underlying data stays granular, transparent, and accurate. That is the work, and it is the thread that ties together everything on my schedule this week.

Where to Find Me in Vegas

I am on stage (and at a lunch table) a couple of times this week. Come say hi.

EventSessionWhen / Where
BSides Las VegasPanel: I am CVE, AMA!, with Tod Beardsley, Lindsey Cerkovnik, Madison Ficorilli, and Katie Noble (Common Ground track)Wed, Aug 5, 12:00-12:45pm PT, Tuscany Suites
Black HatPanel Luncheon: Universal Zero Trust in the Age of Autonomous Exploitation, with Dr. Chase Cunningham and Vikram Bedi (JP Morgan Chase)Thu, Aug 6, 12:00-1:30pm PT, Cipriani at the Wynn

The BSidesLV panel is the one I never miss. Last year we ran out of time before we ran out of questions, so bring the hard ones. The Black Hat luncheon is the one I am most curious about, because “what defenders do when AI collapses the gap between discovery and exploitation” is exactly the problem I moved to Empirical to work on. Seats are limited, so grab one if the topic is your thing (the free lunch from Cipriani does not hurt).

Fair warning: both of my sessions are in the noon slot, so a few of the talks I recommend below run at the same time. Choose wisely. I will be at DEF CON too, so if you want to meet up there, just reach out.

The Talks I’d Clear My Calendar For

Enough about me. I went through all three schedules and pulled the CVE, vulnerability, and exploitation talks that made my own must-see list, grouped by con and in rough time order. One theme jumps out of every program this year: AI is now doing vulnerability research at scale, and the gap between discovery and exploitation is collapsing. That is the exact thread running through my Black Hat panel, so I am biased, but the lineups back it up.

BSides Las Vegas

Black Hat

DEF CON 34

Let’s Connect

Summer Camp is, and always has been, about the people. If you want to talk CVE data, EPSS, and predictive VM, or just trade stories from the hallway track, find me. I will have a fresh run of stickers to hand out, so track me down before they are gone.

You can find me on LinkedIn, X, Bluesky, and infosec.exchange, or just yell my name in a hallway at any of the three cons. It usually works.

And tell me: what is the one talk you are not missing this year? I am always looking to fill the gaps in my own schedule.

See you in the desert. Stay hydrated.


One More Thing: Breakfast?

Still reading? Then you have earned an invite.

RogoLabs presents: Breakfast Forecast
Decoding Risks: From Omelets to Zero-Days

Quick context, since the top of this post is all Empirical: RogoLabs is my personal open-source research lab, the shingle I hang my side projects under when I am off the clock. Once a year, it also does breakfast.

  • When: Friday, Aug 7 (DEF CON), 8:00 AM
  • Where: The Peppermill, Las Vegas
  • Seats: Capped at 20, so this one is for the folks who made it to the bottom of the post
  • RSVP: [email protected] or Signal jgamblin.01

First come, first served. Bring your appetite and your hardest questions.

A digital illustration of the Las Vegas skyline at twilight from a desert viewpoint. Overlaid over the scene are intricate, glowing, and colorful holographic data visualizations, including 3D scatter plots, network graphs, and flowing waveforms.

CVE Mid-Year 2026 Check-In: Volume Vertical, Exploitation Rare

We are halfway through 2026, so it is time for the mid-year CVE check-in. The short version: the volume curve has gone vertical while exploitation has not. This review covers everything published in the first half of 2026 (Jan 1 – Jun 30, 2026), the volume, the severity, what is actually being exploited, and who is driving the numbers, all measured against the same elapsed window a year ago so a partial half is never compared to a full one.

TL;DR

The first half of 2026 produced 35,364 CVEs, more in six months than any full year before 2024 (all of 2023 finished at 28,817). That works out to one new CVE every 7.4 minutes, an increase of 49.5% over the same window in 2025 (23,656). And yet only 85 of them (0.24%) have made CISA’s KEV list so far, a floor that will rise as the cohort ages and exploitation is confirmed. That gap is the story of 2026 so far: we are minting CVEs faster than ever while confirmed exploitation stays rare, so the hard problem is signal-to-noise, not patch volume.

At this pace the year projects to roughly 71,314 to 72,008, and the all-time catalog has now passed 344,258 CVEs since 1999.

Note: All statistics in this report exclude rejected CVEs to provide an accurate count of active vulnerabilities.

Key Statistics at a Glance

MetricValue
Total CVEs (H1 2026)35,364
CVEs per Day195.4
Change vs same window 2025+49.5%
Projected Full Year71,314 – 72,008
Critical Severity3,554
High Severity13,821
Average CVSS Score6.89
CVSS Coverage94.3%
CWE Coverage95.6%
Active CNAs340
Rejected CVEs (H1 2026)1,265
Already Known-Exploited (KEV)85

H1-over-H1: Three Years Side by Side

To keep the comparison honest while 2026 is still in progress, each year is measured over the identical window (January 1 through Jun 30).

WindowCVEsPer DayAvg CVSS
Jan 1 – Jun 30, 202420,374112.66.65
Jan 1 – Jun 30, 202523,656130.76.57
Jan 1 – Jun 30, 202635,364195.46.89

Forecast Scorecard: Are We On Pace?

At 195.4 CVEs/day, two straight-line methods land close to each other (both are simple extrapolations of the same H1 run, so this is a sanity check, not two truly independent signals): the run-rate extrapolates to 71,314, and a seasonality-adjusted estimate (scaling the pace across the full half, then dividing by 2025’s 49% first-half share) to 72,008.

CVEForecast, one of my own RogoLabs tools, projects 90,831 CVEs for full-year 2026 (LinearRegression, MAPE 17.9), so I am partly arguing with my own model here. That is 18,823 above the top of the straight-line range, and here is where I will plant a flag: I think the model is high. Both simple extrapolations land near 72,008, and the forecast’s entire gap to them rests on a heavy second-half surge that still has to show up. My call is the year closes nearer 72,008 than 90,831. I will happily eat those words in the December review if H2 accelerates the way the model expects, but the burden of proof is on the surge.


What Changed in H1 2026

GitHub Security Advisories is the busiest CNA at 6,801 assignments. New to the most-affected product list this year: Chrome, OpenClaw. Among weakness types, CWE-862 (Missing Authorization) climbed to #2 in the top five.

Spotlight: OpenClaw. A project that barely existed a year ago, OpenClaw (Peter Steinberger’s viral local AI agent, the subject of Lex Fridman Podcast #491) is already one of the most-reported products of the half with 537 CVEs. The striking part is who is doing the reporting: VulnCheck alone assigned 500 of them (93%), disclosed steadily across the half rather than in a single dump. That concentration says more about researcher attention than code quality: VulnCheck, whose remit is emerging and exploited-in-the-wild threats, is exactly the kind of team that systematically covers a fast-growing new target, and concentrated third-party research on a hot AI agent is the coverage you would want. To its credit the project embraced the CVE lifecycle itself, issuing advisories through GitHub as reports came in. I track its CVEs at OpenClawCVEs.


Historical CVE Growth

To compare like with like, this chart counts only the first half of every year (January 1 through Jun 30). On that basis 2026 already stands taller than any prior first half: more CVEs in six months than the same window has ever produced.

First-half growth has been relentless, and 2026 is +49.5% on the first half of 2025.

Counting full years, the cumulative catalog has now passed 344,258 CVEs.


Monthly Distribution (H1 2026)

CVE publications varied across the first half of 2026, with Jun being the peak month at 7,454 CVEs.


Publication Patterns by Day of Week

Publishing clusters midweek. Wednesday is the busiest day at 7,943 CVEs, with Tuesday close behind at 7,216. Patch Tuesday is part of the story, but the midweek bulge owes as much to the high-volume CNAs (GitHub, Linux, the WordPress plugin crowd) that batch-publish midweek.

Weekdays average 6,517 CVEs against just 1,389 on weekends.


Busiest Days of H1 2026

Some days saw massive spikes in CVE publications:

Top 5 Busiest Days

RankDateCVE Count
12026-06-09747
22026-06-17732
32026-05-27716
42026-03-25606
52026-05-12554

CVSS Score Analysis

The Common Vulnerability Scoring System (CVSS) helps standardize severity assessments. Here’s how H1 2026 CVEs were distributed across the scoring range.

The average CVSS score for H1 2026 was 6.89, with a median of 7.10.

Severity Breakdown

SeverityCountPercentage
Critical3,55410.0%
High13,82139.1%
Medium14,48541.0%
Low3,0568.6%
Unscored4481.3%

Percentages are of all H1 2026 CVEs; “Unscored” are the 1.3% with no CVSS severity assigned.

CVSS Trends Over Time


Top Weakness Types (CWE)

The Common Weakness Enumeration (CWE) categorizes the types of security weaknesses. Here are the most prevalent weakness types in H1 2026:

Top 5 CWEs in H1 2026

RankCWENameCount
1CWE-79XSS3,783
2CWE-862Missing Authorization1,704
3CWE-89SQL Injection1,445
4CWE-22Path Traversal1,264
5CWE-416Use After Free1,037

CVE Numbering Authorities (CNAs)

The leaderboard increasingly reflects where modern software and modern vulnerability research live: platform and ecosystem CNAs (GitHub, Patchstack) and dedicated research CNAs (VulnCheck, VulDB) alongside the traditional product vendors. High assignment counts are not inflation, a CNA covering the WordPress plugin ecosystem or issuing a CVE per kernel fix is doing exactly its job; the low KEV overlap below reflects how rare confirmed exploitation is across all sources, not the validity of any CNA’s records. The most active assigners this year:

Top 5 CNAs in H1 2026

RankCNACVEs Assigned
1GitHub Security Advisories6,801
2VulDB3,319
3VulnCheck3,273
4Patchstack2,704
5Linux2,564

In total, 340 unique CNAs assigned CVEs in H1 2026.


Top Vendors

The vendors with the most CVEs attributed to their products this year (each links to its NVD search):

Top 5 Vendors in H1 2026

RankVendorCVE Count
1Linux2,564
2Google1,801
3Microsoft864
4OpenClaw537
5Oracle445

Most Vulnerable Products

Drilling past vendors to specific products, the H1 2026 leaders:

Top 5 Products

RankProductCVE Count
1Linux Kernel1,956
2Chrome1,203
3OpenClaw534
4Windows 10372
5Android303

Product-level counts can differ slightly from the vendor totals above: a vendor’s CVEs may span several products, and a single CVE can name more than one.


Known-Exploited Vulnerabilities (CISA KEV)

Volume is the headline, but exploitation is what should actually drive patching. Of the 35,364 CVEs published in H1 2026, only 85 (0.24%) have shown up in the CISA KEV catalog so far. Treat that as a floor, not a verdict: KEV is a US-government catalog that lags disclosure by months and records only confirmed, observed exploitation, so this share will climb as the 2026 cohort ages. Even so, the signal holds, most CVEs are not known-exploited, so exploitability (KEV plus a forward-looking score like EPSS) beats chasing raw counts.

Note these are two different populations: the 85 above are H1-2026-published CVEs already in KEV, while CISA added 146 entries to KEV during the half (more than the 132 added in the same window of 2025, many of them older CVEs newly exploited), and 17 of those additions are tied to known ransomware campaigns.

H1 2026 CVEs Already in KEV

A sample (5 most recent of 85):

CVEVendorProductAddedRansomware
CVE-2026-48558SimplehelpSimpleHelp2026-06-29No
CVE-2026-20230CiscoUnified Communications Manager2026-06-25No
CVE-2026-12569PtcWindchill and FlexPLM2026-06-25No
CVE-2025-67038LantronixEDS50002026-06-23No
CVE-2026-34910UbiquitiUniFi OS2026-06-23No

Data Quality

Not all CVEs have complete metadata. Here’s how data quality has evolved over the years:

H1 2026 Data Quality Metrics

MetricCoverage
CVSS Score94.3%
CWE Classification95.6%
CPE Identifiers59.0%

This is where two ideas from the CVE Decaf work I did with Jay Jacobs get practical: actionable data quality (judge a record by whether it is complete enough to act on, not by abstract completeness) and data provenance (knowing which source asserted each field). The CPE gap is the clearest case. At 59.0% CPE coverage, nearly half of H1 2026 CVEs cannot be automatically matched to a product the day they publish, so for those records the answer to “can I act on this today?” is no, no matter how complete the rest of the entry looks. Scoring each record on its provenance (who supplied it) and on the fields that actually drive action (CPE for asset matching, KEV and EPSS for exploitability) is how you turn the raw feed into a measurable signal-to-noise ratio instead of a flat backlog.


Rejected CVEs

Not all CVE IDs stay active. Some are rejected for duplicates, disputes, or invalid submissions, and the rejection rate is a useful read on the ecosystem’s quality control.

H1 2026 Rejection Statistics

MetricValue
Rejected CVEs in H1 20261,265
H1 2026 Rejection Rate3.45%
Total Rejected (All Time)17,648

CVE rejections occur for several reasons:

  • Duplicates: The same vulnerability assigned multiple CVE IDs
  • Disputes: Vendor disagreement that the issue is a vulnerability
  • Invalid: Not a security vulnerability or insufficient information
  • Withdrawn: CVE withdrawn by the assigning CNA

Conclusions

Key Takeaways from the First Half of 2026

  1. Volume keeps climbing: 35,364 CVEs in roughly six months, up 49.5% on the same window last year, with the full year projecting to 71,314-72,008.
  2. Severity stays heavy: 17,375 CVEs (49.1%) are Critical or High.
  3. Web and access-control flaws lead: XSS, Missing Authorization, SQL Injection, Path Traversal headline the CWE list. Memory-safety issues barely register in the top tier this half.
  4. The CNA mix is shifting: platform teams and aggregators, not the original vendors, now top the assigner list, and the lineup reshuffled from a year ago.
  5. Coverage gaps persist: CVSS and CWE are well covered, but CPE sits at 59.0%, which still hampers automated matching.
  6. Confirmed exploitation stays rare (so far): just 85 of 35,364 H1 CVEs (0.24%) are in CISA KEV today, a floor that rises as the cohort ages. Volume is a triage problem, not a patch-everything problem.

What this means for you

  • If you defend a network: do not let the raw count set your pace. Only 0.24% of H1 CVEs are confirmed-exploited in KEV today, but KEV lags and is a floor, not the full risk picture. Lead with exploitability (KEV as a hard floor, EPSS with a threshold you pick), then weight by your own context: internet-facing and sensitive systems jump the queue regardless of score, and compliance SLAs (PCI, FedRAMP, and the like) still set hard clocks. Lower priority is not never, so park the rest in a managed cycle rather than ignoring it.
  • If you run a CNA: the leaderboard now runs through platforms, ecosystems, and research CNAs. Volume reflects scope, not padding; the differentiator that is still genuinely uneven is data quality, and the biggest gap, CPE coverage, is largely an NVD-side enrichment problem rather than a function of who assigned the CVE.
  • If you consume NVD data: enrichment is the bottleneck. CPE at 59.0% means nearly half of new CVEs lack a formal CPE, which complicates NVD-style automated matching (many CNAs still carry vendor/product strings), and volume only widens that gap.

What I’m watching in H2

My call from the scorecard stands: 2026 closes nearer 72,008 than the 90,831 forecast. Two things would change my mind: a December disclosure surge bigger than 2025’s, or another OpenClaw-style project flooding the catalog. The year-end review settles it.


Methodology and Reproducibility

Two primary data sources, plus two enrichment feeds:

  1. NVD JSON – National Vulnerability Database export from nvd.handsonhacking.org
  2. CVE List V5 – Official CVE records from CVEProject/cvelistV5
  3. Forecast – CVEForecast full-year projection
  4. Exploitation – CISA KEV catalog

Everything here is reproducible. The full pipeline (Python, pandas, matplotlib) is on GitHub at jgamblin/H12026CVEBlog, and it leans on the free CVE tooling I build at RogoLabs: cve.icu, cnascorecard.org, and cveforecast.org.

Data collected and analyzed on July 01, 2026.